udpate hashmap
This commit is contained in:
 ranwenjie
@@ -10,6 +10,10 @@ java 中 hashmap的实现原理。
|
||||
* hash冲突如何解决(链表和红黑树)? 为什么hashmap中的链表需要转成红黑树?
|
||||
|
||||
|
||||
好的哈希函数会尽可能地保证 计算简单和散列地址分布均匀,但是,再好的哈希函数也不能保证得到的存储地址绝对不发生冲突。
|
||||
|
||||
|
||||
|
||||
```
|
||||
public class HashMap<K,V> extends AbstractMap<K,V>
|
||||
implements Map<K,V>, Cloneable, Serializable {
|
||||
@@ -96,6 +100,9 @@ final Node<K,V> getNode(int hash, Object key) {
|
||||
|
||||
### put(key, value) 方法
|
||||
|
||||
|
||||
hash存储的过程是: key -> hashcode -> hash -> indexFor()
|
||||
|
||||
```
|
||||
public V put(K key, V value) {
|
||||
return putVal(hash(key), key, value, false, true);
|
||||
@@ -103,6 +110,7 @@ public V put(K key, V value) {
|
||||
|
||||
final V putVal(int hash, K key, V value, boolean onlyIfAbsent,
|
||||
boolean evict) {
|
||||
|
||||
Node<K,V>[] tab; Node<K,V> p; int n, i;
|
||||
if ((tab = table) == null || (n = tab.length) == 0)
|
||||
n = (tab = resize()).length;
|
||||
@@ -147,6 +155,17 @@ public V put(K key, V value) {
|
||||
```
|
||||
|
||||
|
||||
```
|
||||
//返回数组下标
|
||||
static int indexFor(int h, int length) {
|
||||
return h & (length-1);
|
||||
}
|
||||
```
|
||||
|
||||
这里用的位运行,而不是取模操作; 位运算性能更高。
|
||||
|
||||
|
||||
|
||||
## Hash冲突
|
||||
|
||||
HashMap是怎么处理hash碰撞的?
|
||||
@@ -161,12 +180,12 @@ HashMap是怎么处理hash碰撞的?
|
||||
static final int DEFAULT_INITIAL_CAPACITY = 1 << 4; // aka 16, 为啥用位运算呢?直接写16不好么?
|
||||
```
|
||||
|
||||
为什么需要扩容?
|
||||
### 为什么需要扩容?
|
||||
|
||||
主要为缓解哈希冲突造成的外挂链表太长,造成查询性能低下。
|
||||
|
||||
|
||||
HashMap的扩容方式? 负载因子是多少? 扩容时机?什么时候会触发扩容?
|
||||
### HashMap的扩容方式? 负载因子是多少? 扩容时机?什么时候会触发扩容?
|
||||
|
||||
HashMap 中 `final float loadFactor` , loadFactor 默认 0.75 , 也就是达到容量的 75%时就会开始扩容。
|
||||
|
||||
@@ -255,7 +274,8 @@ final Node<K,V>[] resize() {
|
||||
|
||||
|
||||
|
||||
扩容后元素怎么重排到新的容器中,直接复制拷贝可以吗?
|
||||
### 扩容后元素怎么重排到新的容器中,直接复制拷贝可以吗?
|
||||
|
||||
扩容会 rehash,复制数据等耗时操作。
|
||||
|
||||
|
||||
@@ -271,6 +291,14 @@ final Node<K,V>[] resize() {
|
||||
|
||||
## 问题
|
||||
|
||||
|
||||
### JDK7 和 8 HashMap 有什么区别?
|
||||
|
||||
* JDK8 实现引入红黑树,优化链表过长的查询效率
|
||||
* 1.7 采用头插法,1.8采用尾插法
|
||||
|
||||
|
||||
|
||||
### 链表上使用的头插还是尾插方式?
|
||||
|
||||
|
||||
@@ -319,6 +347,18 @@ h & (length-1)` 就是取 hashcode 的低 4位
|
||||
|
||||
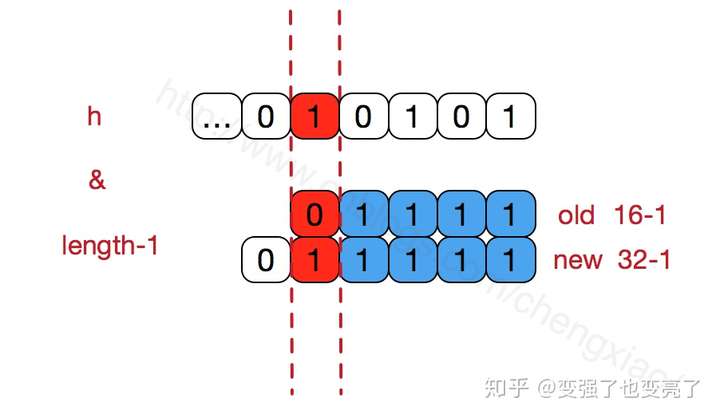
length 保持为 2 的幂, 那么length-1就会变成一个mask, 它会将hashcode低位取出来,hashcode的低位实际就是余数,和取余操作相比,与操作会将性能提升很多。
|
||||
|
||||
另外,hash扩容时 rehash 操作,只有 hash二进制 高位是 1 的hash key 需要 移动到新的 slot (pos + oldCap), 高位是 0 的 key 不需要移动
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Reference in New Issue
Block a user